What is Avian?
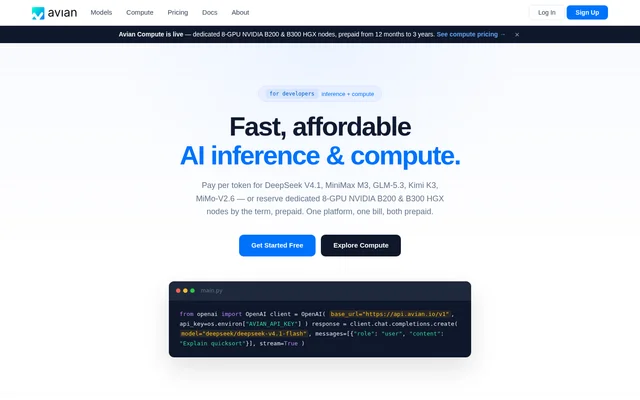
Avian is an AI infrastructure service offering hosted language model inference and dedicated NVIDIA GPU compute for developers. Avian brings token-based API access and reserved GPU nodes into the same service, supporting both coding tools and production APIs. The inference offering includes models from the DeepSeek, MiniMax, GLM, Kimi and MiMo families.
Avian separates access into serverless inference and dedicated compute. Avian inference uses an OpenAI-compatible endpoint with prepaid token billing, while dedicated compute provides complete, single-tenant HGX nodes. This distinction lets developers use hosted models without reserving hardware, or reserve a full node when dedicated capacity is required.
What Avian can do
Avian provides model access, coding-tool compatibility and GPU reservations through its inference and compute offerings. Avian hosts inference models on NVIDIA B200 GPUs with speculative decoding and exposes the models through a single API key. The source also lists privately hosted models, zero data retention and Microsoft Azure infrastructure.
- Avian serves DeepSeek, MiniMax, GLM, Kimi and MiMo models through an OpenAI-compatible API.
- Avian works with Cursor, Claude Code, Cline, Windsurf, Kilo Code and Aider.
- Avian supports streaming responses in the supplied Chat Completions example.
- Avian provides dedicated NVIDIA B200 and B300 HGX nodes with a full NVLink domain.
- Avian allows inference requests without rate limits while prepaid credits remain.
How Avian works
Avian API access begins with an API key and prepaid credits. Avian deducts the token cost of each request from the account balance, and unused credits never expire. The supplied Python example uses the OpenAI client with the base URL https://api.avian.io/v1, an Avian API key and a model identifier.
Avian follows the OpenAI Chat Completions format, allowing developers to change the base URL in an existing OpenAI SDK workflow. Avian dedicated compute follows a separate reservation process: customers select complete NVIDIA B200 or B300 nodes, prepay the reservation term and lock the rate at order.
Who Avian is for
Avian targets developers building with AI, including users of coding assistants and teams deploying production APIs. Avian also serves customers seeking guaranteed GPU capacity through dedicated reservations. The source positions token-based inference as a starting point for teams that may later add dedicated nodes as their compute requirements grow.
- Avian supports coding assistant workflows in compatible development tools.
- Avian provides hosted language model access for production API applications.
- Avian offers reserved, single-tenant GPU capacity for teams needing dedicated nodes.
Avian pricing and plans
Avian inference uses prepaid, pay-per-token billing with no subscriptions, monthly fees or minimum spend. DeepSeek V4.1 Flash costs $0.1275 per million input tokens and $0.51 per million output tokens. Avian publishes separate input, output and cache prices by model, and all listed models are available to users who add credits.
Avian dedicated compute requires a complete node with the whole term prepaid upfront. Available reservation terms run from 12 months to 3 years, with locked rates. The pricing table lists NVIDIA B200 from $3.42 per GPU per hour and NVIDIA B300 from $4.65 per GPU per hour for the longest term.
Avian strengths and limitations
Avian combines an OpenAI-compatible API, multiple model families and non-expiring prepaid credits without inference subscriptions. Avian also states zero request-data retention, GDPR and CCPA compliance, and SOC/2 approved Microsoft Azure infrastructure. Dedicated compute adds single-tenant capacity, but its purchase requirements and geographic availability differ from the token-based inference service.
- Avian inference requires an available prepaid credit balance.
- Avian dedicated compute requires a complete node and full-term upfront payment.
- Avian dedicated compute is available in North America, specifically the US, only.
- Avian lists shorter dedicated reservation terms as sold out.
Avian FAQ
What is Avian?
Avian is an AI inference and dedicated GPU compute service for developers. Avian offers hosted models through an OpenAI-compatible API and reserves complete NVIDIA B200 or B300 HGX nodes for customers needing dedicated capacity.
Is Avian free?
Avian charges for inference using prepaid token credits and for dedicated compute using prepaid reservation terms. Avian lists no subscriptions or monthly fees for inference, and credits never expire. The Get Started Free wording does not specify a free usage allowance.
Does Avian work with the OpenAI API and coding tools?
Avian follows the OpenAI Chat Completions format and supports existing OpenAI SDKs by changing the base URL to https://api.avian.io/v1. Avian lists compatibility with Cursor, Claude Code, Cline, Windsurf, Kilo Code and Aider.
Does Avian have API rate limits?
Avian states that inference requests have no rate limits while the account has prepaid credits. Each request deducts its token cost from the balance, making the available credit balance the stated limit on continued API usage.
Can you rent dedicated GPUs from Avian?
Avian offers dedicated NVIDIA B200 and B300 GPUs as complete, single-tenant HGX nodes. Avian requires a complete node reservation with the entire term prepaid, offers locked rates, and lists dedicated compute availability in the US only.
Does Avian store request data?
Avian states that request data is not retained and that code and data remain within its SOC/2 approved Microsoft Azure infrastructure. Avian also states GDPR and CCPA compliance and describes its models as privately hosted.
From the community
No reviews yet
Be the first to review this tool. What you write helps the next person choose.