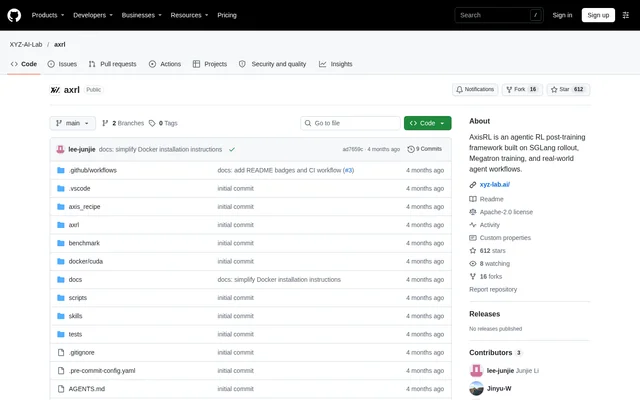
What is AxisRL?
AxisRL is an open-source framework for agentic reinforcement learning post-training built around SGLang rollout and Megatron training. AxisRL coordinates the system layer between agent interactions and model updates, including data movement, resource scheduling, weight synchronization, and reproducible debugging. The project addresses multi-turn workflows involving tools, environments, verifiers, and rewards rather than only single-turn question answering.
AxisRL keeps SGLang and Megatron as the core serving and training engines. Recipes define task-specific behavior, while shared framework components manage rollout scheduling, sample construction, trainer input, and consistency checks. This separation supports workflows with different environment loops, reward logic, context management needs, and resource requirements.
What AxisRL can do
AxisRL combines configurable policy optimization with mechanisms for coordinating agent rollout and training. AxisRL supports both environment loops defined within the framework and external harnesses connected through an OpenAI-compatible proxy. Additional capabilities address long-running trajectories, repeated context, large payloads, and differences between serving and training execution.
- AxisRL supports PPO, GRPO/GRPO2, GSPO, TOPR, TIS, and related optimization variants.
- AxisRL uses partial rollout to hand completed or partially completed samples to trainers earlier.
- AxisRL moves heavy payloads through handles for trainer workers to read on demand.
- AxisRL uses prefix-tree merge and MagiAttention to reduce repeated attention computation.
- AxisRL compares token-level differences through mismatch analysis.
- AxisRL saves training state and relevant data for spike replay.
How AxisRL works
AxisRL runs a loop in which rollout actors execute task-specific agent workflows and SGLang workers serve model generation. Environments, tools, verifiers, or external harnesses produce interaction records and rewards. Megatron workers consume the resulting training samples, and updated weights return to the rollout side. A lightweight driver manages scheduling, lifecycle, metrics, phase transitions, and metadata.
AxisRL recommends the project Docker image, which includes SGLang, Megatron Core, MagiAttention, Ray, CUDA dependencies, and recipe packages. Installation inside the container uses pip install -e . Recipe scripts serve as the main entry points, and most configuration fields can be overridden from the command line. Search-R1 also requires a retrieval server.
Who AxisRL is for
AxisRL serves technical users building agentic post-training workflows with task-specific tools, environments, verifiers, and rewards. White-box recipes suit math, search, and simple tool environments where the environment loop belongs inside AxisRL. Black-box integration targets existing harnesses, including OpenHands and browser tasks, where model interactions need to be captured for training.
- AxisRL provides GSM8K recipes for GRPO-style and PPO math training.
- AxisRL provides Search-R1 for retrieval-augmented multi-turn search training.
- AxisRL demonstrates OpenHands execution inside E2B sandboxes for black-box training.
- AxisRL supports investigation of routing mismatch and intermittent training spikes.
AxisRL pricing and access
AxisRL is available as an open-source project through its public GitHub repository under the Apache-2.0 license. The documented access path is to use the project container, install the repository, and launch a recipe. Model and dataset downloads are optional; users can instead adjust recipe paths for a narrower run.
AxisRL strengths and limitations
AxisRL combines task-specific recipes with shared scheduling, data handling, synchronization, and debugging infrastructure. AxisRL gives particular attention to rollout-trainer consistency through boundary tests, routing replay checks, mismatch analysis, and spike replay. These capabilities support inspection of differences in tokenization, context packing, log probabilities, routing, and weight versions that can affect training behavior.
- AxisRL default recipes assume a GPU machine with enough resources for their configured parallelism.
- AxisRL marks the OpenHands/E2B recipe as work in progress, with configuration and proxy interfaces subject to change.
- AxisRL requires an E2B API key, cloudflared, and an E2B template for the documented default black-box setup.
- AxisRL warns that the optional bulk download can be large because it includes multi-billion-parameter models.
AxisRL FAQ
What is AxisRL?
AxisRL is an open-source agentic reinforcement learning post-training framework built on SGLang rollout and Megatron training. AxisRL coordinates multi-turn agent workflows, training samples, resource scheduling, weight synchronization, and debugging around those serving and training engines.
Is AxisRL open source?
AxisRL is an open-source project available from a public GitHub repository under the Apache-2.0 license. AxisRL documents installation inside its recommended Docker environment and uses recipe scripts as the main entry points for training workflows.
What can you train with AxisRL?
AxisRL includes recipes for GSM8K math training with PPO or GRPO, retrieval-augmented multi-turn search with Search-R1, and black-box agent training with OpenHands/E2B. The OpenHands/E2B recipe is marked as work in progress.
Does AxisRL support external agent harnesses?
AxisRL supports external agent harnesses through an OpenAI-compatible proxy that captures model inputs, outputs, metadata, and rewards for training. The documented black-box recipe runs OpenHands inside E2B sandboxes, but its configuration, launch scripts, and proxy interfaces may change.
What do you need to run AxisRL?
AxisRL recommends its project Docker image and a GPU machine with enough resources for the selected recipe's default parallelism. The image includes serving, training, attention, scheduling, and CUDA dependencies. Search-R1 additionally uses a retrieval server.
How does AxisRL debug training instability?
AxisRL provides mismatch analysis, routing replay checks, and spike replay to investigate rollout-trainer differences and training spikes. AxisRL can save weights, optimizer state, data, and relevant routing information before a spike update so the same update can be replayed for inspection.
From the community
No reviews yet
Be the first to review this tool. What you write helps the next person choose.