What is llm_wiki?
llm_wiki is an open-source desktop application for building a personal knowledge base from documents. A language model organizes imported material into linked wiki pages and maintains those pages as sources change. The application supports research, reading, personal growth, business, and general knowledge projects through scenario templates.
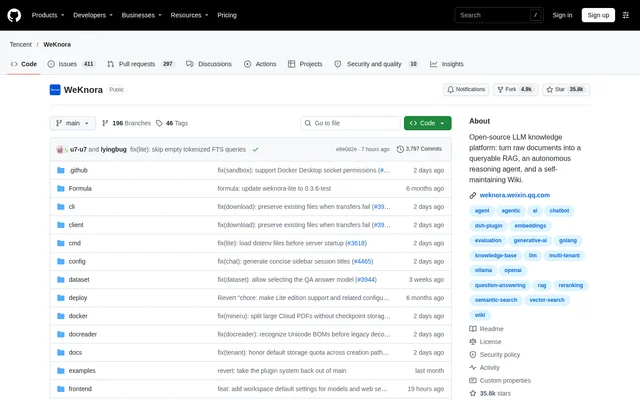
llm_wiki implements Andrej Karpathy’s LLM Wiki pattern as a cross-platform desktop application maintained by nash_su. The underlying structure separates immutable raw sources, generated wiki content, and configuration rules. Rather than deriving knowledge again for each query, llm_wiki incrementally compiles a persistent wiki that people curate while the language model maintains its content.
What llm_wiki can do
llm_wiki combines document processing, wiki generation, retrieval, and graph analysis. Imported sources can become summaries, entity pages, concept pages, and cross-references, with source information retained in page metadata. Search and chat can draw on the wiki or original materials, while graph tools expose relationships and areas that need more coverage.
- llm_wiki imports PDFs, Office documents, ebooks, images, media, web clips, and URL batches.
- llm_wiki extracts embedded PDF images and generates captions using a vision model.
- llm_wiki visualizes linked pages and discovers knowledge communities.
- llm_wiki offers optional embedding-based retrieval through LanceDB.
- llm_wiki searches the web through Tavily, SerpApi, or SearXNG and ingests results.
- llm_wiki previews agent-generated Markdown, HTML, images, and other workspace files.
How llm_wiki works
llm_wiki analyzes a source before generating wiki files. The analysis identifies entities, concepts, arguments, connections, and contradictions; generation then produces linked pages, updates navigation records, and creates review items. Content hashing lets unchanged files bypass ingestion, while a persistent queue provides progress visibility, cancellation, retries, and recovery after an application restart.
llm_wiki presents a knowledge or file tree alongside chat and preview panels. Users can configure models per project and route chat and ingestion independently. A Chrome web clipper captures pages, and a local HTTP API with a bundled MCP server exposes search, file reading, graph traversal, and source rescanning to external tools.
Who llm_wiki is for
llm_wiki serves people who want documents and collected web material organized into a maintained knowledge base. Research and reading projects can use source-linked pages to retain context, while personal and business projects can define goals and questions in purpose.md. The wiki directory also works as an Obsidian vault.
- llm_wiki helps research projects connect imported papers and web findings.
- llm_wiki organizes reading materials into linked concepts and source summaries.
- llm_wiki supports personal or business knowledge projects with configurable goals.
- llm_wiki helps users inspect weakly connected topics and unexpected relationships.
llm_wiki access and project portability
llm_wiki is available as an open-source project through its public GitHub repository. The supplied page does not describe commercial plans or subscription prices. Model providers are configurable, including custom providers and OpenAI-compatible embedding endpoints. Complete project archives can be exported and imported across devices, and existing wiki pages can be used to rebuild the index.
llm_wiki strengths and limitations
llm_wiki combines persistent wiki generation with traceable sources, incremental updates, and graph-based exploration. Source-only retrieval provides a mode that answers exclusively from imported originals. Folder monitoring and cached ingestion reduce repeated processing, while project migration and Obsidian compatibility make the generated knowledge base usable beyond a single application session.
llm_wiki keeps human judgment within the workflow rather than treating every generated result as final. The review system flags items for evaluation and offers predefined actions. Model-dependent capabilities also involve configuration: chat and ingestion can use different models, and vector retrieval is optional rather than an unconditional part of every project.
- llm_wiki requires users to configure models for model-dependent workflows.
- llm_wiki sends flagged review items to people for judgment.
- llm_wiki uses optional embeddings when vector search is enabled.
llm_wiki FAQ
What is llm_wiki?
llm_wiki is an open-source, cross-platform desktop application that turns documents into an organized, interlinked knowledge base. A language model incrementally generates and maintains persistent wiki pages, with source references connecting generated content to the original imported material.
What file formats does llm_wiki support?
llm_wiki supports PDF, Office documents, EPUB/MOBI, Org mode, images, media, web clips, and batches of URLs. PDF processing can use built-in, cloud, or local MinerU options, and image ingestion can extract embedded PDF images and generate factual captions with a vision model.
Does llm_wiki have an API or MCP integration?
llm_wiki includes a local HTTP JSON API and a bundled MCP server for hybrid search, file reading, graph traversal, and source rescanning. A ready-made agent skill also supports installation into Claude Code or Codex through a command.
Can llm_wiki answer only from original sources?
llm_wiki provides a Read Sources Only mode that answers exclusively from original imported material. Generated wiki pages also include source references in YAML frontmatter, allowing users to trace wiki content back to contributing raw files.
Does llm_wiki work with Obsidian?
llm_wiki creates a wiki directory that works as an Obsidian vault. Generated pages use wikilink cross-references and YAML frontmatter, while index.md serves as the content catalog and navigation entry point for the language model.
How does llm_wiki keep a knowledge base updated?
llm_wiki monitors external changes in the source folder and synchronizes ingestion and deletion cleanup. Incremental caching skips unchanged files, while a persistent processing queue supports crash recovery, cancellation, retries, and visible progress.
From the community
No reviews yet
Be the first to review this tool. What you write helps the next person choose.