What is marin?
marin is an open-source framework, research program, and community for developing foundation models. The project primarily concerns training large language models, from preparing raw data through evaluating trained models. Researchers and developers can use the software to structure experiments and examine the processes behind model development.
marin follows an open development approach that records processes, experiments, and decisions as they happen. Failed experiments are included in that record rather than excluded from the published account. The project's core collaborators come from Stanford CRFM and Open Athena, and its documentation is available on ReadTheDocs and in the repository.
What marin can do
marin covers the data and training stages involved in foundation model development. The repository combines experiment workflows with released research artifacts, including the Delphi scaling suite. Beyond language models, the project reports use of its library for building audio-text, DNA, and protein models.
- marin supports data curation, transformation, filtering, and tokenization.
- marin supports language model pretraining, posttraining, and evaluation.
- marin executes experiment steps according to their dependencies.
- marin supports training on mixtures of datasets.
- marin can scale training workflows to GPU pods, TPU pods, and multislice TPUs.
- marin provides Delphi checkpoints, recipe code, and reproducible training mixture pipelines.
How marin works
marin experiments consist of steps that can depend on one another and execute in topological order, similar to a Makefile. The supplied TinyStories example defines a tokenized dataset and a training step. The training step depends on the dataset step, ensuring that tokenization finishes before model training begins.
marin's example uses a lazy dataset handle, so defining the tokenization step does not immediately download data. A step runner executes the lowered training experiment. The repository explains that modifications can extend this workflow to larger models, larger datasets, dataset mixtures, and larger accelerator configurations.
Who marin is for
marin serves researchers and developers working on foundation models, especially large language models. The project also supports library-based experiments beyond language modeling. Its current research includes mixture-of-experts models intended for tasks important to scientists and researchers, while Delphi addresses how model configurations and performance relate to compute budgets.
- Researchers can use marin to investigate language model training recipes.
- Developers can use marin to build dataset preparation and training workflows.
- Scaling researchers can examine marin's Delphi checkpoints and plotting data.
- Model researchers can use marin for audio-text, DNA, and protein experiments.
marin pricing and access
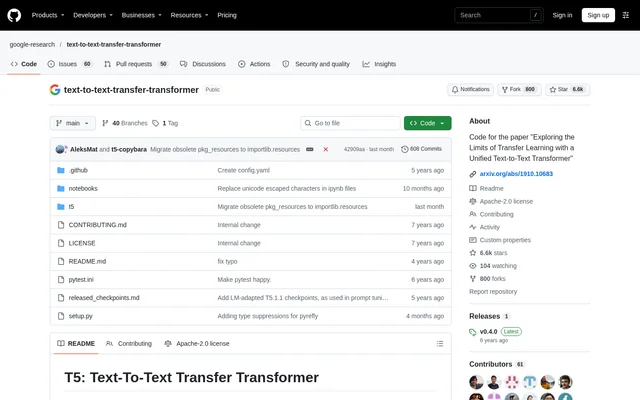
marin is available as an open-source project through its public GitHub repository under the Apache-2.0 license. The repository provides installation guidance, training examples, contribution instructions, and links to documentation. The supplied project description does not list commercial plans or prices for model training or computing resources.
marin strengths and limitations
marin's strengths include its published development record, dependency-based experiment structure, and released training artifacts. Delphi includes checkpoints for every run, training mixture pipelines, forkable recipe code, and plot-ready data. These resources provide concrete material for examining how the project's models and scaling experiments were developed.
marin requires a technical workflow: the documented starting path involves installing the project and running a code-defined training experiment. The tiny example uses CPU resources, while larger workflows can involve GPU or TPU pods. The repository directs new users toward a tiny language model tutorial before a larger training experiment.
marin FAQ
What is marin?
marin is an open-source framework, research program, and community for foundation model research and development. The project focuses on large language model training, including data preparation, pretraining, posttraining, and evaluation, while openly recording experiments and development decisions.
Is marin free?
marin is available as an open-source project under the Apache-2.0 license through its public GitHub repository. The project description does not list paid software plans or training compute prices; the documented workflow involves installing the software and running experiments.
What can you use marin for?
marin supports data curation, transformation, filtering, tokenization, pretraining, posttraining, and evaluation for foundation models. The project has also been used to build audio-text, DNA, and protein models, and includes a scaling suite for studying language model training recipes.
How do marin experiments run?
marin experiments run as dependency-linked steps executed in topological order, similar to a Makefile. The TinyStories example defines tokenization before training, with the training step depending on the tokenized dataset and a step runner executing the experiment.
Does marin support GPU and TPU training?
marin supports workflows that can scale to large GPU or TPU pods, including multislice TPUs. The repository also provides a tiny model training example configured for CPU resources, and Delphi's scaling suite was trained on the Google TPU Research Cloud.
How do you get started with marin?
marin provides installation guidance and a tutorial for training a tiny language model, followed by an example for a larger experiment. Documentation is available on ReadTheDocs and in the repository's docs folder, with a Discord community for discussion.
From the community
No reviews yet
Be the first to review this tool. What you write helps the next person choose.