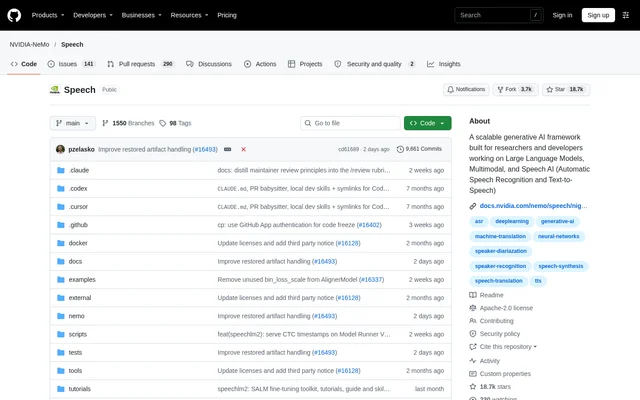
What is NeMo?
NeMo is an open-source speech AI framework for researchers and PyTorch developers building automatic speech recognition, text-to-speech, and speech language models. NeMo supports creating, customizing, and deploying models using existing code and pretrained checkpoints. The repository now concentrates on audio, speech, and multimodal language models rather than the broader set of modalities supported before the repository split.
NeMo provides developer documentation for the latest release and the main development branch. The repository also links to a Hugging Face collection containing open-weight checkpoints and demos. These resources give developers access to model examples and technical guidance alongside the framework source code.
What NeMo can do
NeMo supports several speech AI tasks through its framework and available model checkpoints. The repository describes models for offline and streaming recognition, multilingual speech synthesis, translation, and audio understanding. Capabilities vary by model, so language coverage, latency controls, and transcript features should be checked against the selected checkpoint.
- NeMo supports automatic speech recognition for recorded and streaming audio.
- NeMo supports text-to-speech model development and multilingual speech synthesis.
- NeMo provides speech models with multilingual transcription and translation capabilities.
- NeMo includes an offline speech LLM that supports instructions and vocabulary context.
- NeMo offers a speech model that produces speaker-attributed transcripts with word timestamps.
- NeMo supports speech LLM development using existing code and pretrained checkpoints.
How NeMo works
NeMo recommends installation from source with uv to reproduce the actively tested dependency stack from the committed lockfile. Developers can instead use a prebuilt NGC Docker image or build the container from source. A pip installation option allows developers to add NeMo to an existing compatible Python and PyTorch environment without replacing the installed PyTorch build.
NeMo requires Python 3.12 or above and PyTorch 2.7 or above. Training requires an NVIDIA GPU with CUDA, while GPU acceleration is recommended for inference. The documentation distinguishes the tested container stack from the minimum requirements, allowing compatible alternative environments rather than requiring the exact versions shipped in the container.
Who NeMo is for
NeMo is intended for researchers and PyTorch developers working on speech models. The workflow suits technical users who want to reuse pretrained checkpoints, customize model behavior, or deploy speech AI models within a compatible computing environment. The repository provides documentation, examples, tutorials, and installation instructions rather than presenting NeMo as a standalone consumer transcription application.
- NeMo helps researchers customize speech recognition models.
- NeMo supports developers building multilingual transcription and speech translation workflows.
- NeMo supports teams developing speech synthesis and speech language models.
NeMo pricing and access
NeMo is available as an open-source project under the Apache License 2.0. Developers can obtain the source repository, install the package through pip, or use the documented container options. The supplied GitHub subscription prices describe GitHub services, not NeMo plans, and do not establish a paid subscription model for the framework.
NeMo strengths and limitations
NeMo combines reusable model code, pretrained checkpoints, and several installation paths for speech AI development. The tested lockfile and container offer reproducible environments, while pip supports compatible existing installations. NeMo still requires technical setup, and the repository explicitly identifies hardware requirements for training and a narrower current scope following the repository split.
- NeMo requires an NVIDIA GPU and CUDA for training.
- NeMo requires a compatible Python and PyTorch software environment.
- NeMo directs users needing additional pre-split modalities to release v2.7.3.
NeMo FAQ
What is NeMo?
NeMo is an open-source framework for creating, customizing, and deploying speech AI models. NeMo targets researchers and PyTorch developers working on automatic speech recognition, text-to-speech, and speech LLMs, using existing code and pretrained checkpoints.
Is NeMo free?
NeMo is available as an open-source project under the Apache License 2.0. NeMo can be obtained through its source repository, pip installation, or documented container options; the supplied page does not list paid NeMo plans.
What can you use NeMo for?
NeMo supports speech recognition, text-to-speech, speech translation, and speech language model development. NeMo provides checkpoints with capabilities including streaming transcription, multilingual recognition, speaker-attributed transcripts, word timestamps, and instruction-guided audio understanding, depending on the selected model.
How do you install NeMo?
NeMo recommends installation from source with uv using the committed dependency lockfile. NeMo also provides a prebuilt NGC Docker container, instructions for building a container from source, and a pip option that preserves a compatible existing PyTorch installation.
Does NeMo require an NVIDIA GPU?
NeMo requires an NVIDIA GPU and CUDA for training, while an NVIDIA GPU is recommended for inference. NeMo requires Python 3.12 or above and PyTorch 2.7 or above, with installation options for compatible existing environments.
Does NeMo still support models beyond speech?
NeMo now focuses on audio, speech, and multimodal LLMs following a repository split. NeMo directs users who need support for additional modalities to v2.7.3, identified in the repository as the final pre-split release.
From the community
No reviews yet
Be the first to review this tool. What you write helps the next person choose.