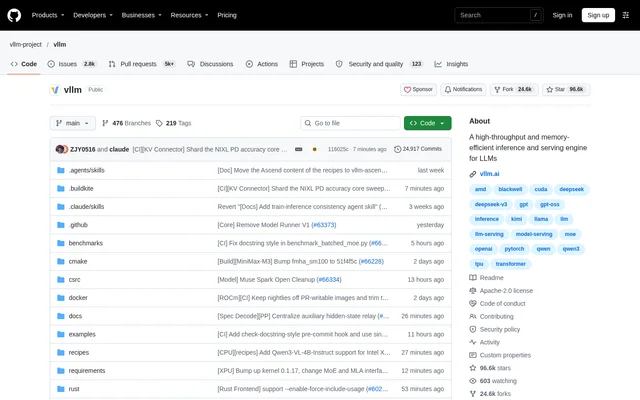
What is vLLM?
vLLM is an open-source inference and serving engine for large language models. vLLM provides a library for running supported models and serving their outputs through API interfaces. Developers and researchers can use vLLM for language generation, multimodal workloads, embeddings, retrieval, and reward or classification model execution.
vLLM originated in the Sky Computing Lab at UC Berkeley and is maintained by a community spanning academic institutions and companies. The repository provides source code, documentation, examples and contribution guidance. The project uses the Apache-2.0 license and links to a research paper about memory management with PagedAttention.
What vLLM can do
vLLM combines attention memory management, request scheduling and model execution capabilities for inference workloads. The repository describes support for popular Hugging Face models, multiple decoding algorithms and several quantization formats. vLLM also includes output controls and API interfaces for incorporating model serving into applications.
- vLLM manages attention key and value memory with PagedAttention.
- vLLM supports continuous batching, chunked prefill and prefix caching.
- vLLM supports quantization formats including FP8, INT8, INT4, GPTQ/AWQ and GGUF.
- vLLM distributes inference through tensor, pipeline, data, expert and context parallelism.
- vLLM generates streaming outputs and structured outputs using xgrammar or guidance.
- vLLM provides tool calling and reasoning parsers.
- vLLM supports an OpenAI-compatible API server, the Anthropic Messages API and gRPC.
How vLLM works
vLLM is installed with uv, which the repository recommends, or pip. The getting-started instructions also include a command to download precompiled kernels for faster startup. Developers can build vLLM from source for development, while the linked documentation provides installation guidance, a quickstart and the supported model list.
vLLM supports NVIDIA, AMD and Intel GPUs alongside x86, ARM and PowerPC CPUs. Additional hardware plugins cover options including Google TPUs, Intel Gaudi, Huawei Ascend and Apple Silicon. Model execution capabilities include CUDA/HIP graphs, optimized attention kernels, speculative decoding and transformations using torch.compile.
Who vLLM is for
vLLM serves developers and researchers who need to run models or expose model inference through APIs. The supported architectures extend beyond decoder-only language models to mixture-of-expert models, hybrid attention and state-space models, multimodal models, embedding and retrieval models, and reward and classification models.
- vLLM can serve decoder-only language models such as Llama, Qwen and Gemma.
- vLLM can run multimodal models such as LLaVA, Qwen-VL and Pixtral.
- vLLM can run embedding and retrieval models such as E5-Mistral, GTE and ColBERT.
- vLLM can support applications that need tool calling or structured model outputs.
vLLM pricing and access
vLLM is available as an open-source project under the Apache-2.0 license, with access through package installation or a source build. The supplied repository text does not list commercial vLLM plans or subscription prices. The accompanying GitHub pricing information describes GitHub services rather than vLLM plans.
vLLM strengths and setup requirements
vLLM combines broad model and hardware support with several serving interfaces. PagedAttention, batching, prefix caching and quantization give developers concrete mechanisms for managing inference workloads. Distributed inference and support for dense and mixture-of-expert LoRA layers add deployment options, while the installation workflow makes vLLM a software component rather than a hosted chat application.
- vLLM requires installation with uv or pip, or a build from source.
- vLLM deployment requires choosing from supported models and hardware.
- vLLM directs users to documentation for installation details and supported model coverage.
vLLM FAQ
What is vLLM?
vLLM is an open-source library for large language model inference and serving. vLLM provides attention memory management, request batching, distributed inference and API serving, with support for language, multimodal, embedding, retrieval, reward and classification models.
Is vLLM free?
vLLM is available as an open-source project under the Apache-2.0 license. The repository provides installation through uv or pip and the option to build from source; the supplied vLLM text does not list commercial plans or subscription prices.
How do you install vLLM?
vLLM can be installed with uv or pip, and the repository recommends uv. The getting-started instructions include downloading precompiled kernels for faster startup. Developers can also build vLLM from source and consult the linked installation documentation and quickstart.
Does vLLM support OpenAI-compatible APIs?
vLLM provides an OpenAI-compatible API server, plus support for the Anthropic Messages API and gRPC. vLLM also supports streaming outputs, structured output generation using xgrammar or guidance, tool calling and reasoning parsers.
What hardware does vLLM support?
vLLM supports NVIDIA, AMD and Intel GPUs, along with x86, ARM and PowerPC CPUs. Additional hardware plugins include Google TPUs, Intel Gaudi, IBM Spyre, Huawei Ascend, Rebellions NPU, Apple Silicon, MetaX GPU and Iluvatar CoreX GPU.
From the community
No reviews yet
Be the first to review this tool. What you write helps the next person choose.